Logistic Regression for Predictive Maintenance: What It Can (and Cannot) Predict
Logistic regression is cheap, interpretable, and well understood — but it answers a narrower question than most maintenance teams think it does, and knowing exactly what that question is decides whether it belongs in the pipeline at all.
Logistic regression keeps reappearing in predictive maintenance pipelines for good reason: it is fast to fit, its coefficients are directly interpretable as the effect of each covariate on failure odds, and it degrades gracefully on the small, messy datasets industrial teams actually have. The recurring mistake is not choosing it — it is expecting it to answer a question it was never built to answer.
Logistic regression is cheap, interpretable, and well understood — but it answers a narrower question than most maintenance teams think it does, and knowing exactly what that question is decides whether it belongs in the pipeline at all.
§ 02What a Binary Failure Classifier Actually Outputs
A logistic regression model trained for maintenance predicts the probability that an asset fails within a fixed window — the next 30 days, the next maintenance cycle — given a snapshot of covariates at scoring time. That is a genuinely different output from a survival model's remaining-useful-life estimate: it tells a planner how urgent an asset is relative to others in the fleet this week, not when, specifically, it is likely to fail. For triage and work-order prioritization, that is often exactly the granularity needed, and cheaper to get right than a full survival model — the failure mode is misreading a well-calibrated urgency score as a timeline.
§ 03Where the Assumptions Break
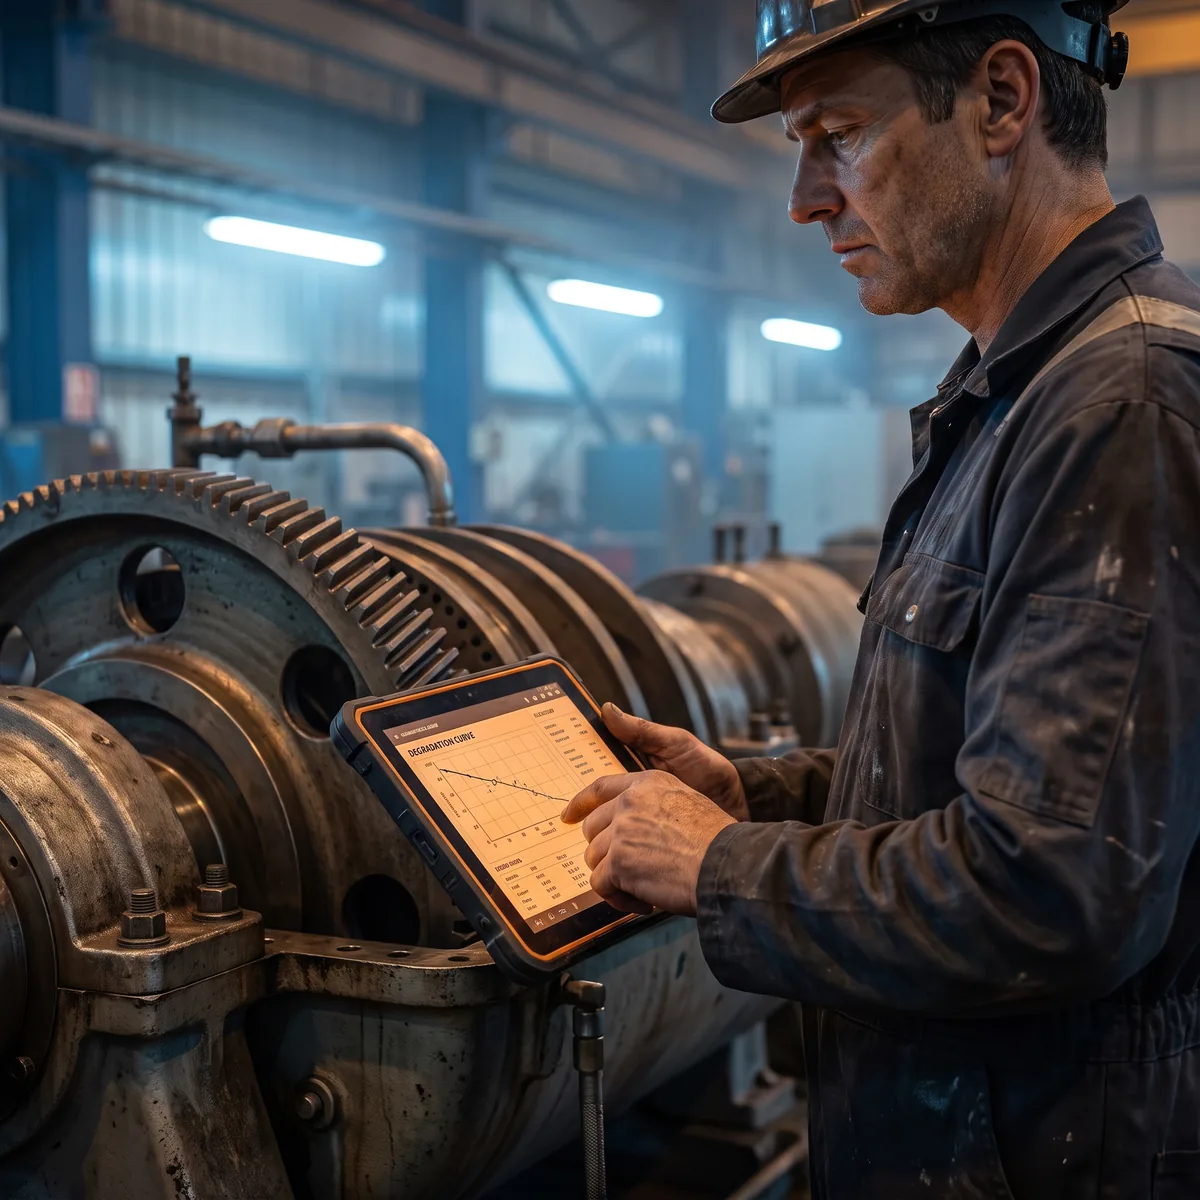
The model assumes a linear relationship between each covariate and the log-odds of failure, which mechanical degradation routinely violates — vibration amplitude's effect on failure risk is rarely a straight line; it is flat for a long stretch and then compounds sharply near end-of-life, a pattern a linear-in-log-odds model only captures if someone manually engineers the right interaction and polynomial terms in advance. The second, quieter failure mode is class imbalance: failures are rare by design in well-maintained fleets, and a model trained without deliberate resampling or class weighting will often reach high accuracy simply by predicting "no failure" for almost everything, which is a useless model dressed up as a good one.
§ 04When It's Still the Right Choice
It earns its place in three situations: as a fast baseline that any more elaborate model has to beat before its added complexity is justified, in genuinely small-data regimes where a tree ensemble or neural model would overfit long before it converges, and wherever a maintenance decision has to be explained to a safety auditor or regulator in terms of specific, named factors rather than a black-box score. None of that is a case against more sophisticated models — it is a case for knowing which of those three conditions actually applies before reaching for one.