How to Forecast Equipment Replacement Timing: The Most Accurate Methods Compared
"Expected life" is a single number that throws away most of the information a maintenance team actually has. Survival analysis and machine learning both do better — but not for the same data, and not by the same margin.
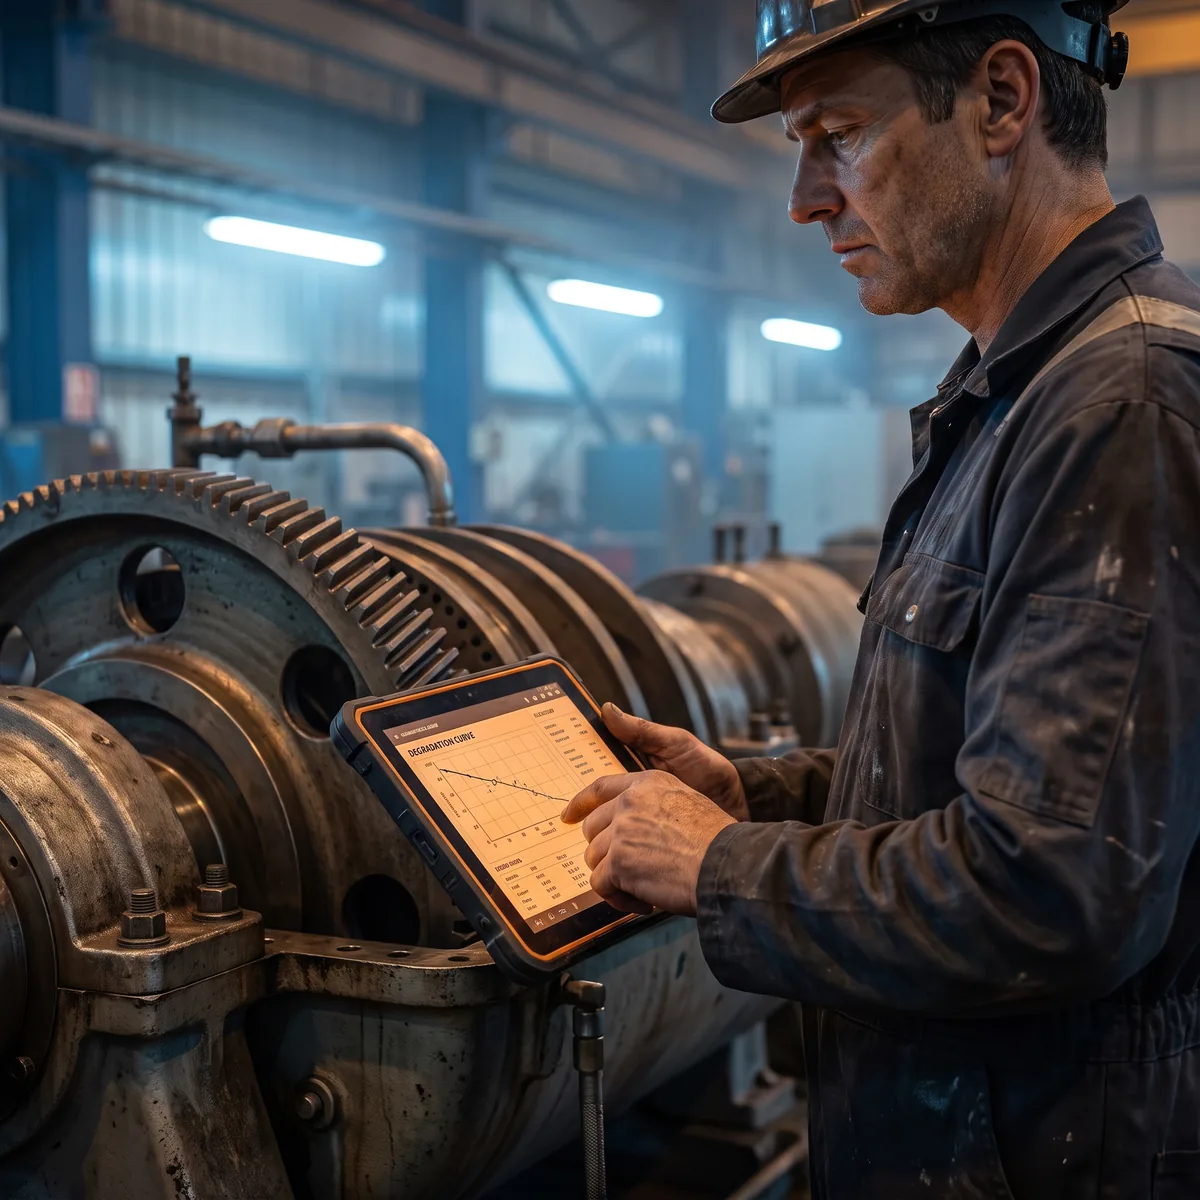
Most replacement-timing decisions still start from an OEM depreciation schedule or a fixed "expected life" figure — a single number, applied uniformly to every unit in a fleet, regardless of duty cycle, environment, or maintenance history. It fails in both directions at once: assets running a harsher cycle than the schedule assumed get replaced too late, after a failure the schedule was supposed to prevent, while assets running a lighter cycle get replaced too early, discarding useful remaining life and inflating capital spend for no safety benefit.
The methods that actually improve on this fall into two families with very different data appetites — classical survival analysis and machine-learning survival models — and the question that matters most is not which is more accurate in the abstract, but which is accurate given the failure history and telemetry a given fleet actually has.
"Expected life" is a single number that throws away most of the information a maintenance team actually has. Survival analysis and machine learning both do better — but not for the same data, and not by the same margin.
§ 02Survival Analysis and the Weibull Distribution
The Weibull distribution is the default starting point in reliability engineering for a specific, practical reason: with just two parameters — a shape parameter β and a scale parameter η — it can represent early-life defects (β < 1), random failures unrelated to age (β ≈ 1), and wear-out failure (β > 1, rising toward higher values as degradation accelerates with age), and which regime a given asset class falls into is itself a useful diagnostic. Just as important is what it does with assets that haven't failed yet: maximum-likelihood fitting treats every still-in-service unit as right-censored data — known to have survived at least this long, exact failure time unknown — rather than discarding it or treating it as a failure at the current date, which is the bias that creeps into naive regression run only on units that have already failed.
§ 03Where Machine Learning Earns Its Complexity
Random survival forests and gradient-boosted survival models (Cox-based or accelerated-failure-time variants) earn their added complexity when there is more to model than age and a handful of static covariates — time-varying sensor telemetry, duty-cycle history, environmental exposure — the kind of rich per-asset data a Weibull curve's two parameters simply cannot absorb. The catch is data volume in a specific and often overlooked sense: these models need enough observed failure events, not just enough running assets, and safety-critical infrastructure is maintained precisely to avoid failing, which means the asset classes with the richest telemetry are frequently the ones with the fewest labeled failures to train on. A model fit on twelve failures and a hundred engineered features will find spurious patterns before it finds real ones.
§ 04Choosing the Right Method for the Data You Actually Have
The practical rule is to size the model to the failure history, not to the ambition: under roughly a hundred observed failure events with mostly static covariates, a Weibull or Cox proportional-hazards baseline will usually out-generalize anything more elaborate, and is far easier to explain to a maintenance planner who has to act on it. Once a fleet has both a meaningful failure count and rich time-series telemetry per asset, a survival forest or gradient-boosted model becomes worth the added complexity — but only if it is benchmarked against the Weibull baseline on held-out concordance and calibration first, since a machine-learning model that fails to beat the two-parameter baseline is not earning its complexity budget. That evaluation discipline is what makes a scoring approach portable across a fleet of very different asset types — the same test applies whether the asset being scored is a rail axle-box, a pump, or a transformer.